CFG-free Distillation: Fast Generation Without Guidance
Eliminating the 2x computational cost of CFG. Achieving same quality with single forward pass.

CFG-free Distillation: Fast Generation Without Guidance
Eliminating the 2x computational cost of Classifier-Free Guidance. Achieving CFG quality with a single forward pass.
TL;DR
- Problem: CFG requires two forward passes (conditional + unconditional) = 2x cost
- Solution: Distill CFG effect into a single model
This part is for subscribers
A subscription unlocks every premium series and its Jupyter notebooks.
You need a free account to subscribe. Cancel anytime.
Related Posts
Consistency Models: A New Paradigm for 1-Step Generation
Single-step generation without iterative sampling. OpenAI's innovative approach using self-consistency property.
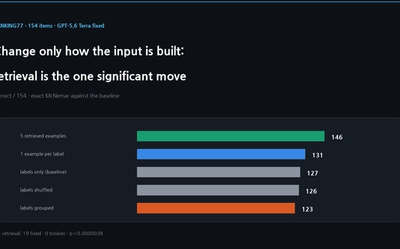
Same Model, Five Ways to Build the Input: Only Retrieval Moved It Significantly
On BANKING77 with GPT-5.6 Terra held fixed, reordering labels, grouping them and changing reasoning effort each moved one or two items in both directions against the baseline, with no significant paired difference. Attaching five retrieved training examples scored 146 of 154, fixing 19 items and breaking none (exact McNemar p about 3.8e-6).
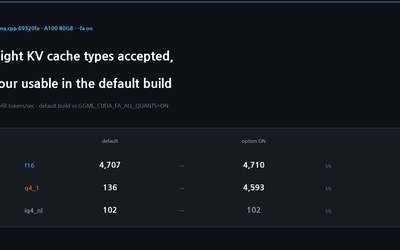
llama.cpp -ctk and -ctv: The Default CUDA Build Supports Four Values
llama-bench accepts eight KV cache types and llama-server accepts nine, but the default CUDA build compiles FlashAttention kernels for only f16, bf16, q8_0 and q4_0, and only when K and V match. Every other setting has no kernel and prefills at 83-284 tokens per second against about 4,600. Measured on llama.cpp 69320fe on an A100.